

Around 80 percent of employees now use AI at work, and only about 40 percent of companies have given them an enterprise solution to use. The distance between those two figures is shadow AI, and in a regulated sector it walks the risk in through the front door. Proprietary information flows into tools the company has never assessed, and the output that comes back can be confidently wrong.
That gap is why we ran our last ZeroTo100 Live session with James Corbett, an AI platform architect who spends his days deploying these systems inside banks and other tightly regulated environments. The session circled one question that every leader in banking, insurance, health, energy, or law will eventually have to answer out loud.
When a regulator asks how your most important automated decisions are made, can you show them?
This piece is the concise version of what we went through in the webinar, around the three things you should prove. At the end of each one there are a few questions worth asking about your own setup. We turned all eighteen of them into a three-minute scorecard, so you can see where you stand before someone with the authority to fine you does.
The reframe: you defend the system, not the model
We tend to talk about approving AI as though the task were to sign off a model. The unit you actually have to defend is the whole system, from input to output. The same model, given different prompts, different documents, and a different place to run, produces different results. So the question a regulator will ask, how do you know this works, needs more than a model’s benchmark score. It needs evidence about the system you built around that model.
That evidence rests on three pillars, and each is also one section of the scorecard.
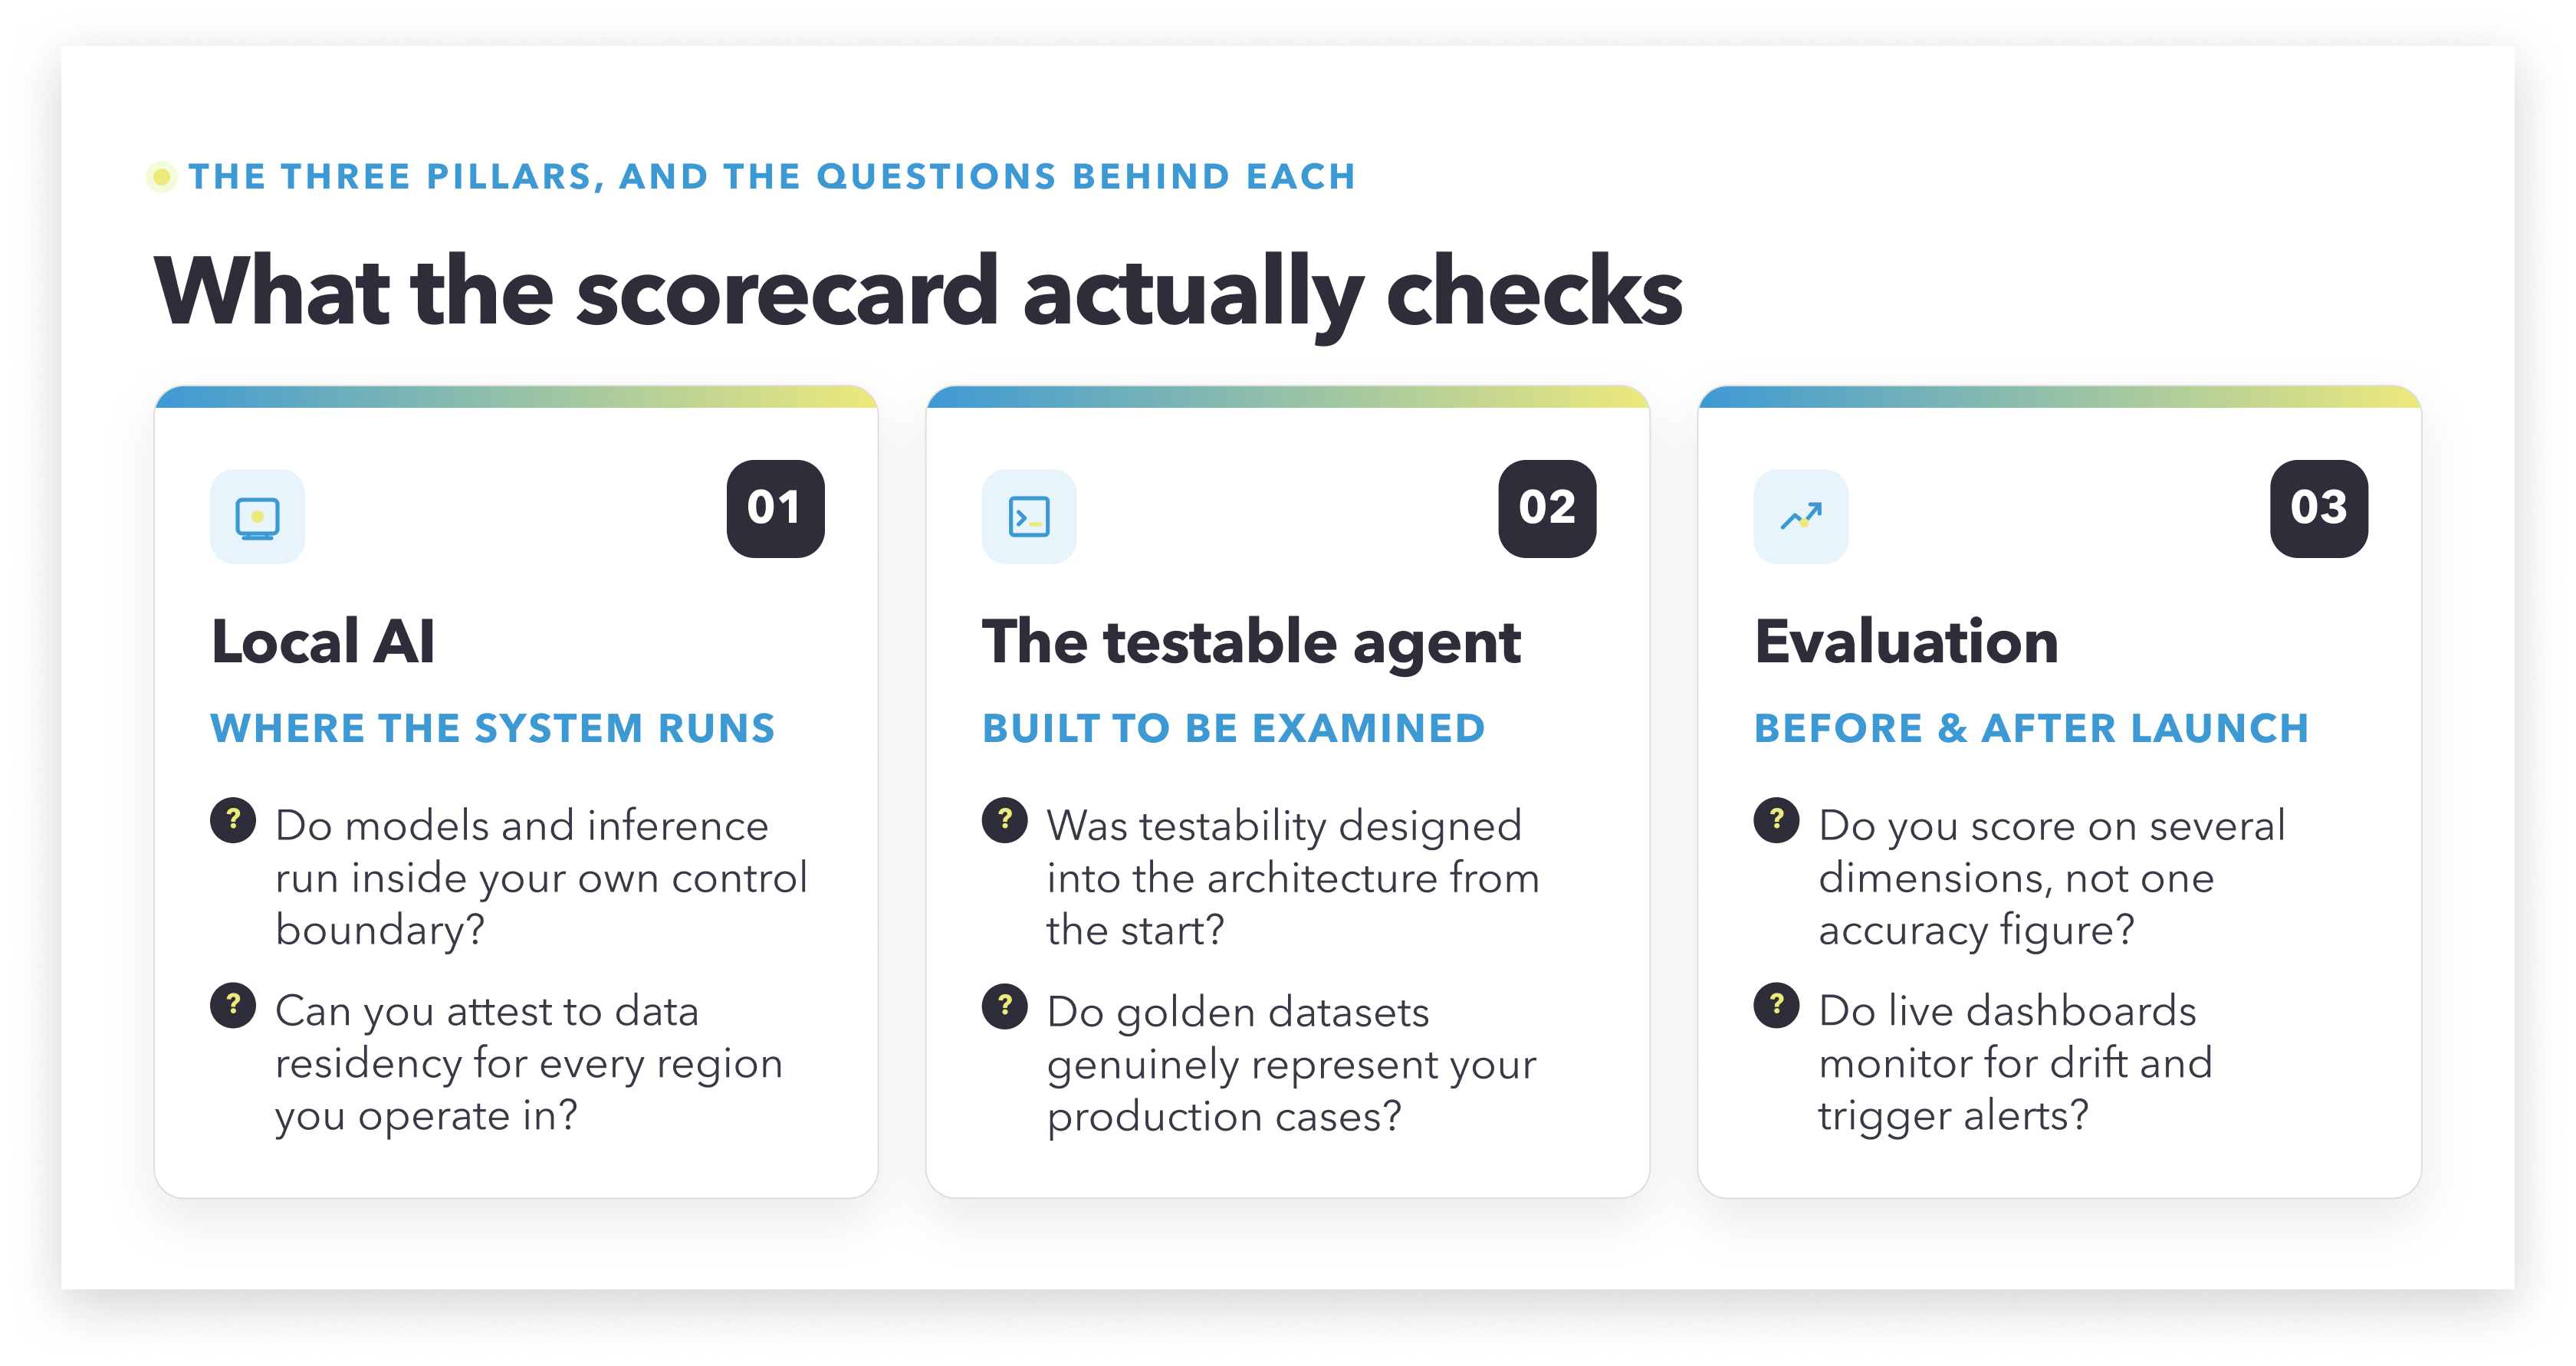
Pillar one: Local AI, or where the system runs
The first decision is where your data, your model, and your audit trail physically sit. This runs along a spectrum. At one end you deploy your own GPUs on premises. In the middle you use a European data centre or a private cloud with zero data retention written into the contract.
The test that matters is whether the data ever leaves a boundary you can name and control. Keeping it inside that boundary removes cross-border data flows and the slow leakage of intellectual property that happens when proprietary context is handed to someone else’s infrastructure.
Ask yourself:
Do your models and inference run inside your own control boundary, a VPC, a data centre, or a device you own?
Can you attest to data residency for every region you operate in, whether that is the EU, MENA, or South Africa?
Is every model interaction captured in a request-level audit log?
Pillar two: the testable agent, built to be examined
An agent built to be examined later has decomposable steps that mirror the real workflow, returns similar outputs from the same inputs, and is sandboxed so it can only reach what its task requires.
With tracing and a golden set of reference cases, you can look inside its reasoning and explain why each decision was made. Explainability stops being an aspiration and becomes a property of the architecture. The catch is that testability has to be designed in from the start. Bolting it on after launch is far harder and rarely complete.
Ask yourself:
Was testability designed into the architecture from the start, or added later?
Do you maintain golden datasets that genuinely represent your production cases?
Does tracing let you see inside the agent’s decisions, and does a versioned test suite run before every release?
Pillar three: evaluation, before and after launch
Offline testing against a golden set gets a system to sign-off. Online evaluation keeps it honest once real users, new documents, and new languages arrive. A second model can act as a judge of live conversations, and drift can be caught by watching how the same question gets answered over time. James was candid that he has never deployed a system that needed no changes once people began using it. Nobody can see how a system will be used in advance, so responsible design assumes it will move.
Ask yourself:
Do you score on several dimensions, or lean on a single accuracy figure?
Do you test explicitly for safety and bias, including protected-class harms, and run adversarial and prompt-injection testing?
Do live dashboards monitor for drift and trigger alerts, and do you keep an incident log as part of the evidence package?
See where you stand in three minutes
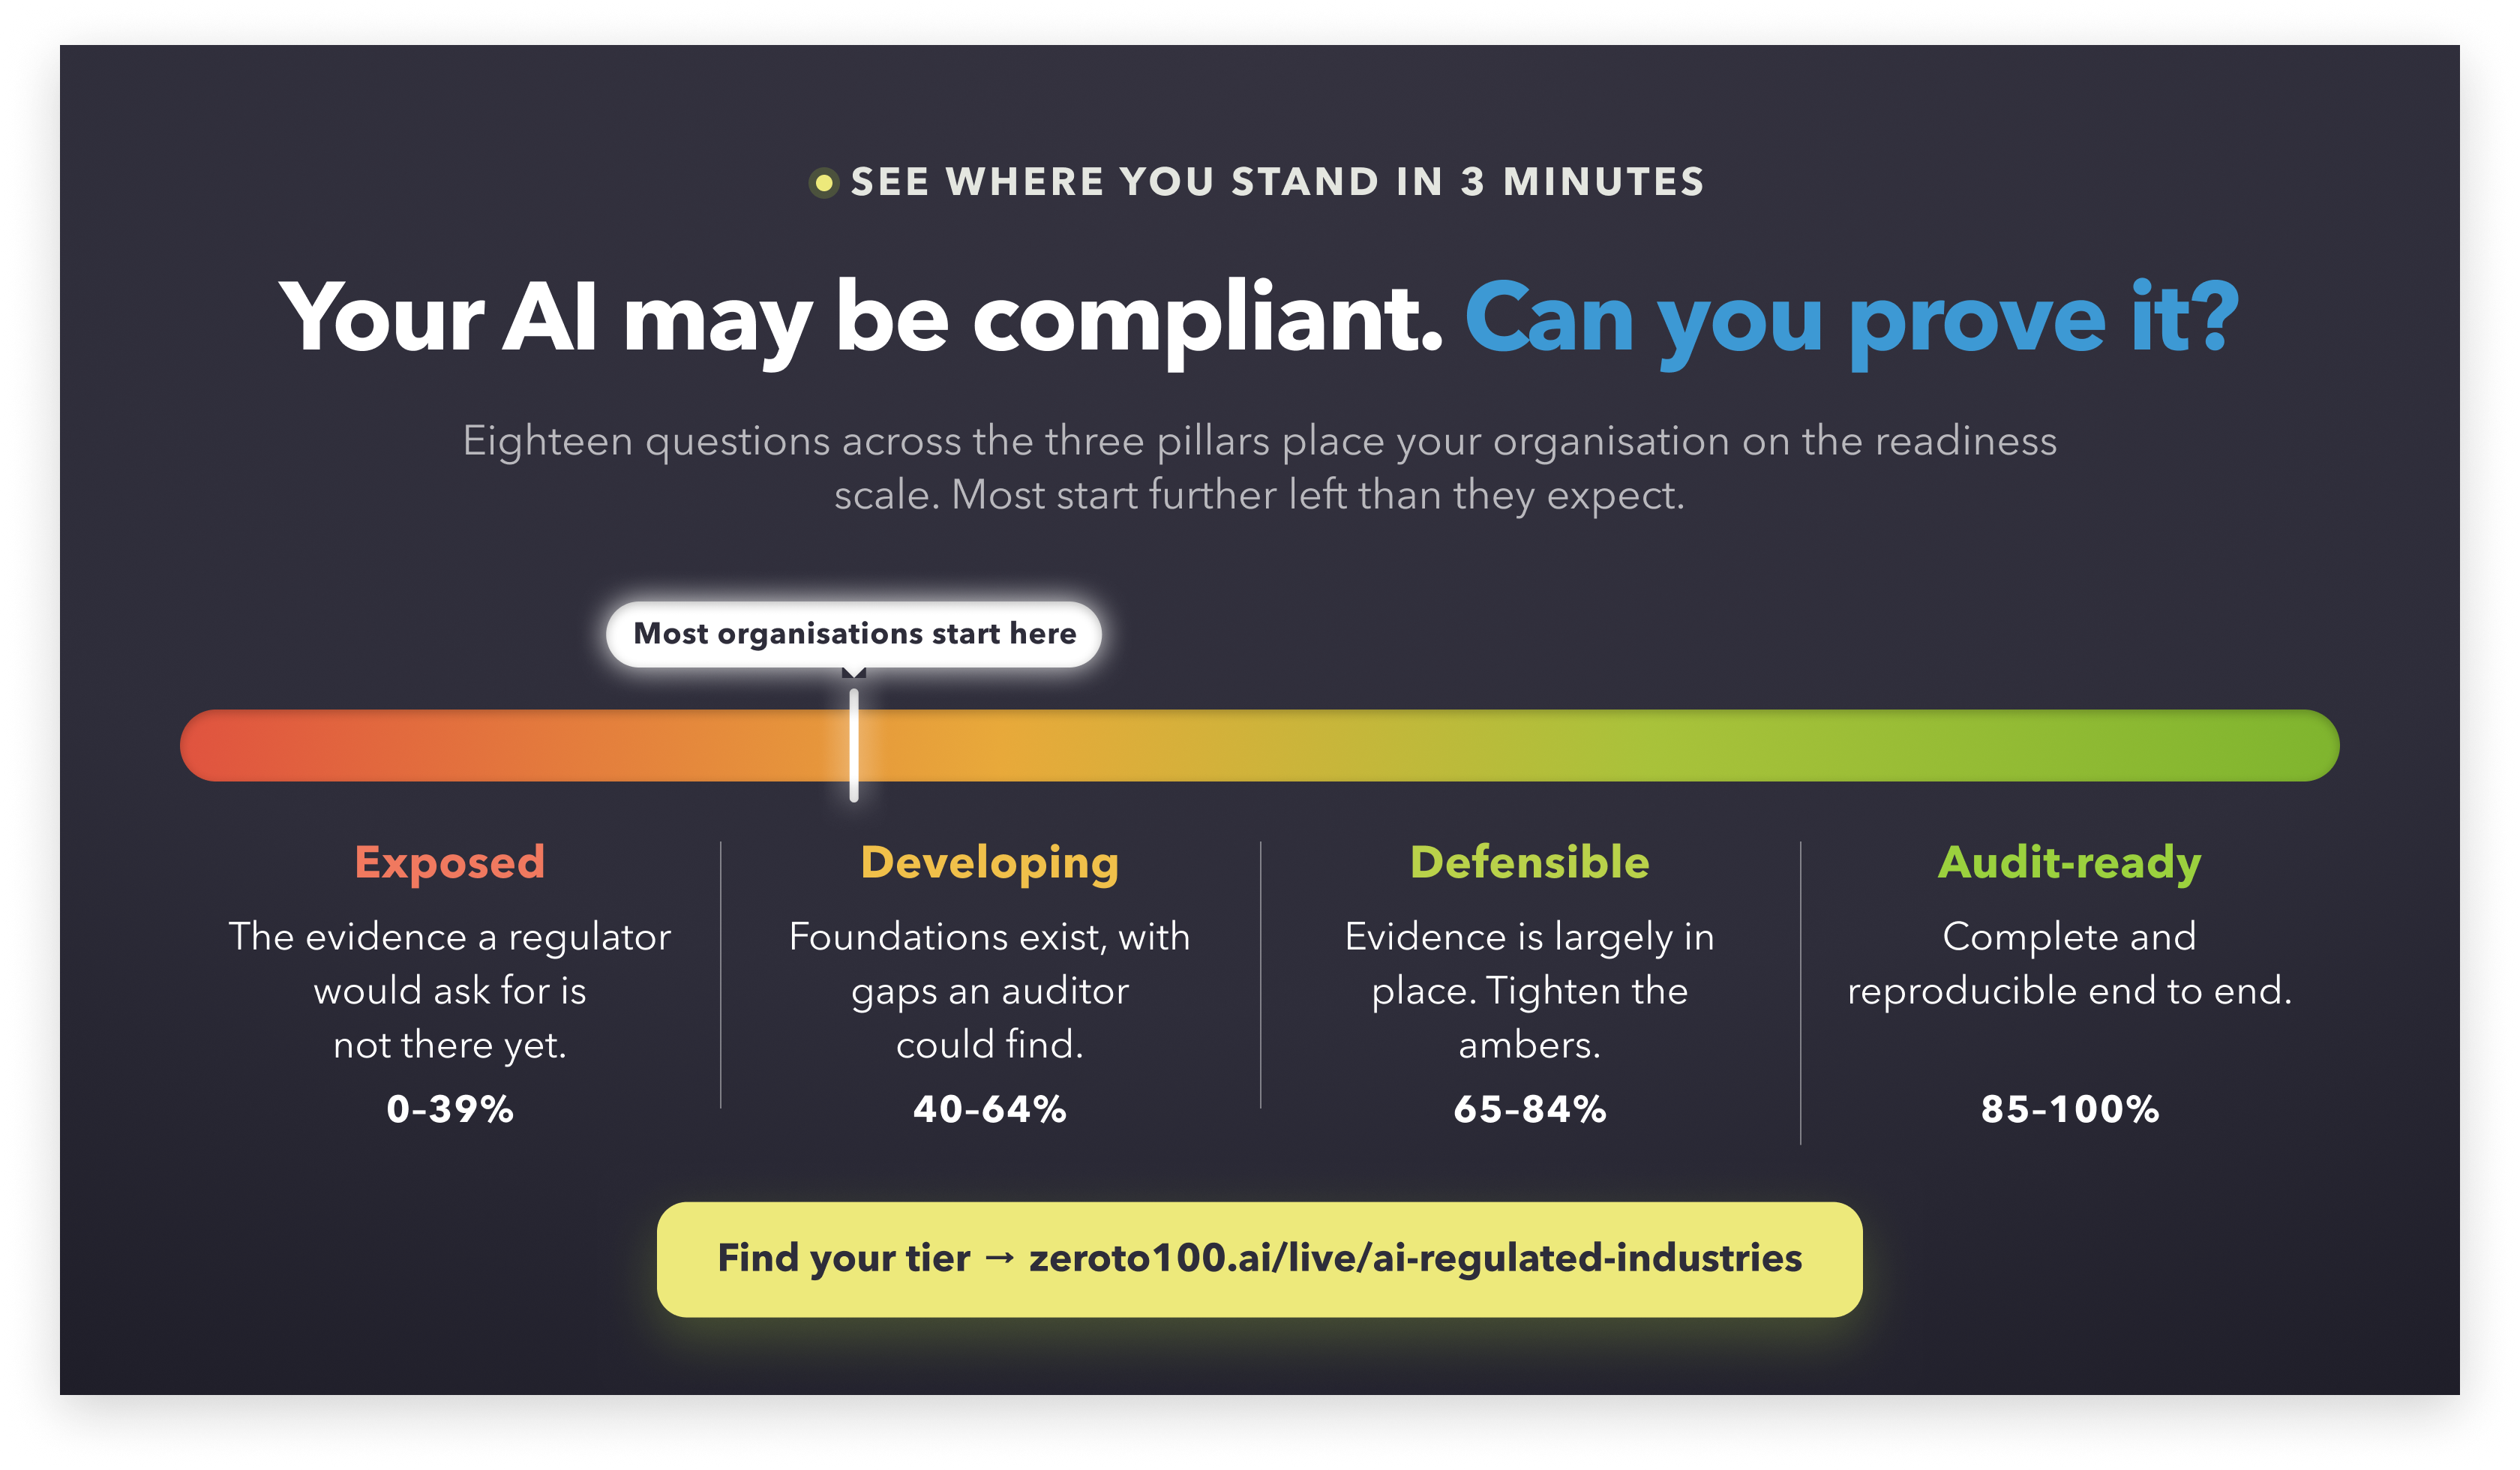
If a few of those questions gave you pause, that is exactly what the scorecard is for. It takes about three minutes: eighteen questions across the three pillars, scored in real time against the controls a regulator actually checks, from data residency and audit logs to testability and your evaluation setup. At the end it places you in one of four tiers, from Exposed through Developing and Defensible to Audit-ready, and shows you the gaps to close first.
Take the scorecard and watch the full recording here
What it looks like when the evidence is there
The payoff is concrete. One compliance team James worked with received hundreds of forms, each carrying hundreds of questions, none of which could be answered wrongly. By hand the work took a week. Rebuilt on structured outputs, where every answer carries its question, its source document, and an explanation, the same forms came back filled in minutes. The structure is what makes the speed safe, because a fixed field can be checked automatically and traced back to its origin.
None of this is free. A small-model sovereign setup runs in the region of 80,000 euros once total cost of ownership is included, and a frontier-level deployment can reach around 500,000 euros across three to five years. Against that cost sits a regulatory clock. The EU AI Act is mostly informational today, but its obligations for high-risk activities, meaning the decisions made about people in lending, hiring, education, and health, come into force in December 2027. The penalties already seen under GDPR reach tens of millions of euros or a share of global turnover, which gives a sense of the seriousness regulators can bring. The evidence package is what stands between your organisation and that exposure.
So the question worth sitting with has little to do with whether your organisation will adopt AI.
It is whether, when someone asks how your most important automated decisions are made, you can show them the answer. The scorecard tells you how close you are today.
Take the scorecard and watch the recording here
*By René Bohnsack. Following our ZeroTo100 Live session with AI platform architect James Corbett on AI in regulated industries, 9 June.*
Thanks, René.
Your “burden of proof” argument made me wonder whether we may be asking the wrong causal question.
When performance improves after AI is introduced, AI rarely arrives alone. The workflow gets redesigned, managers pay more attention, people change how they work, bad process steps suddenly become visible, and teams may simply take the task more seriously because something new has been introduced.
So even if the outcome improves, what exactly are we proving?
That AI created the value?
That AI triggered a better process?
Or that the organization finally questioned a workflow it should have questioned anyway?
The uncomfortable part for me is this: if removing the AI later leaves most of the improvement intact, was the AI really the value creator — or only the intervention that exposed where the value was being lost?
What evidence would let you distinguish those explanations?